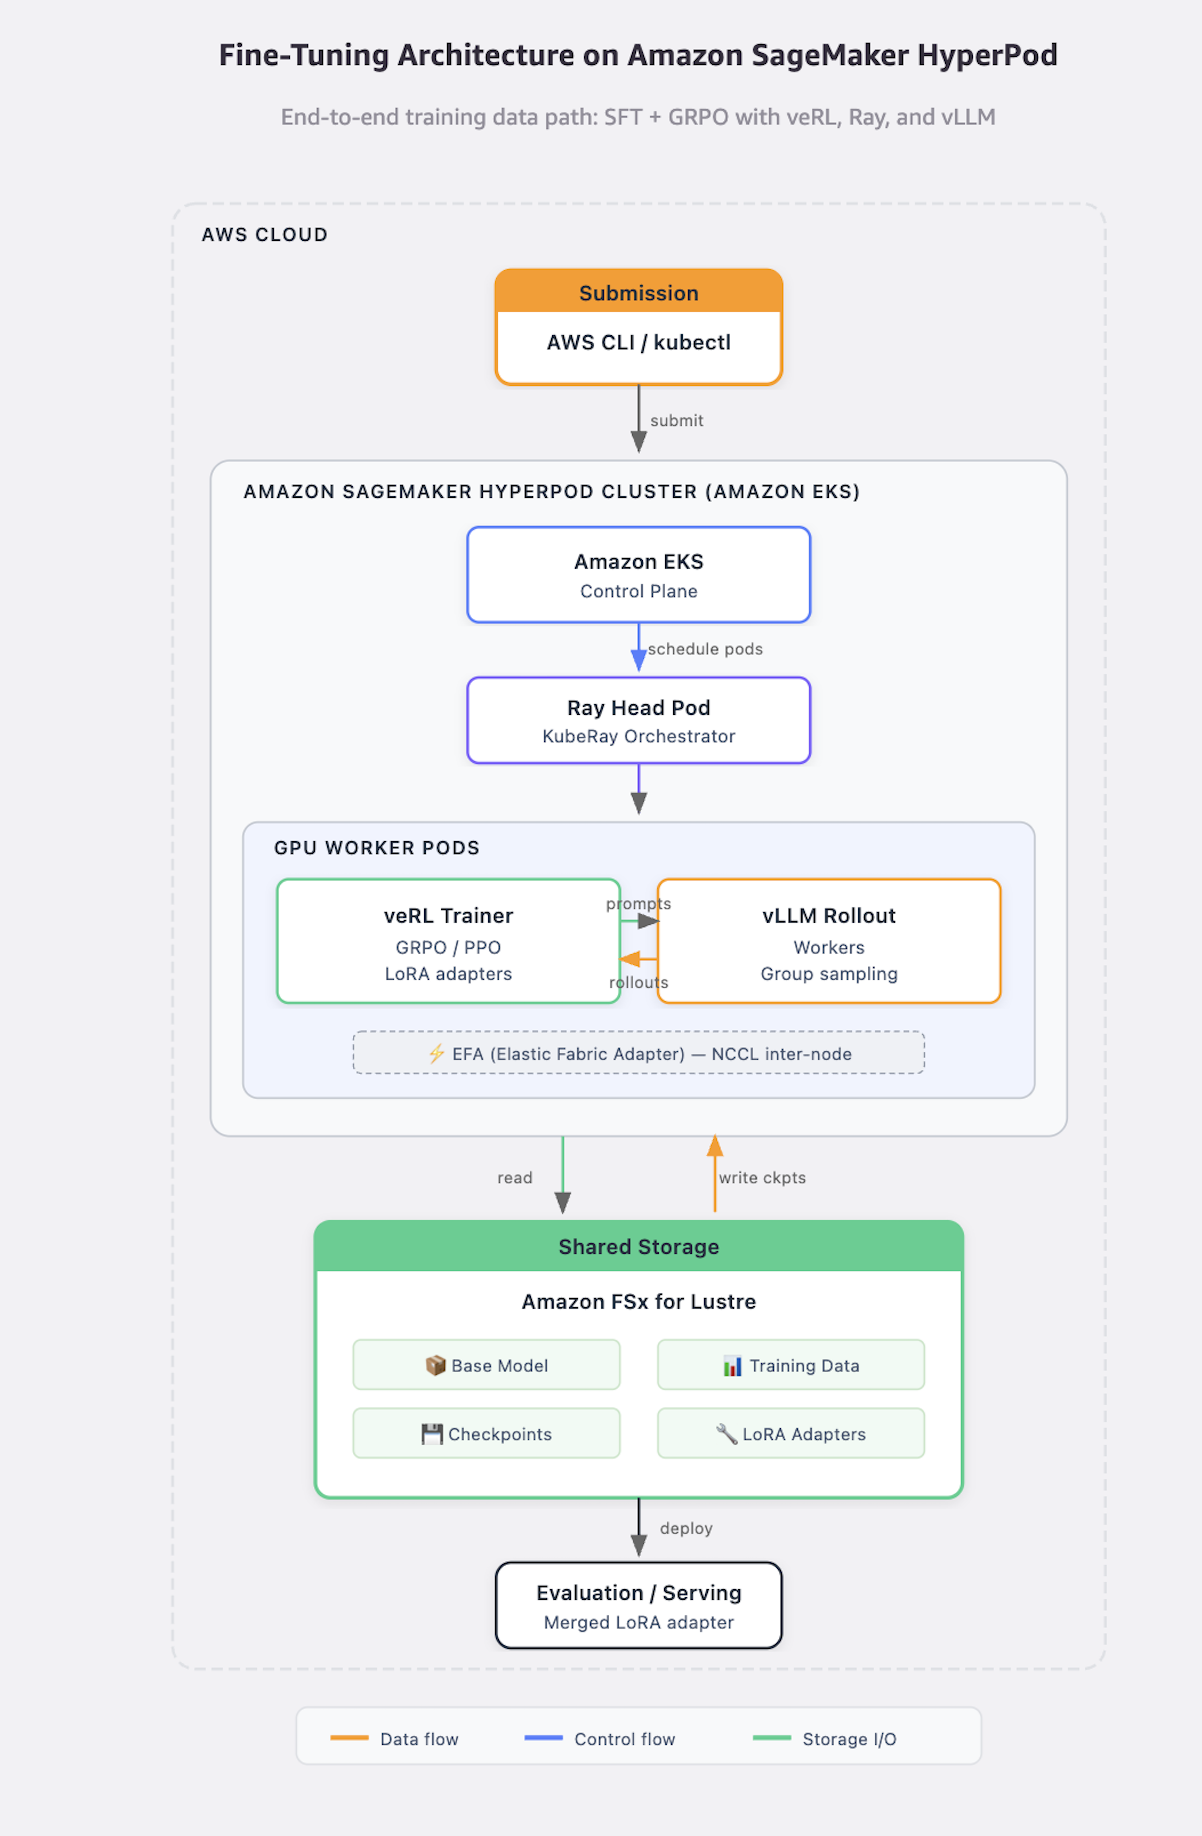
The AWS blog post discusses fine-tuning the GPT-OSS-20B model for multilingual reasoning using Amazon SageMaker HyperPod. It highlights the use of supervised fine-tuning (SFT) and reinforcement learning with GRPO, with SFT improving reasoning-language accuracy from 22% to 100%.